
Supercomputers and cutting-edge AI data centers are fueling the artificial intelligence (AI) revolution. Large-scale systems need comprehensive builds that are increasingly integrated to meet the evolving demands of complex workloads. As AI applications become more sophisticated, the need for infrastructure that’s not only incredibly powerful but also energy-efficient is growing exponentially. Innovations like NVIDIA’s GB200 are designed to deliver the scalability needed for next-generation AI superclusters.
At the 2025 NVIDIA GPU Technology Conference (GTC), VP and Chief Architect of Systems, Mike Houston, and Senior Director of Applied Systems Engineering, Julie Bernauer, discussed large-scale systems design principles in their May 18 presentation, “Next-generation at Scale Compute in the Data Center.”
NVIDIA’s First Rack-Scale Product is the GB200 Superchip
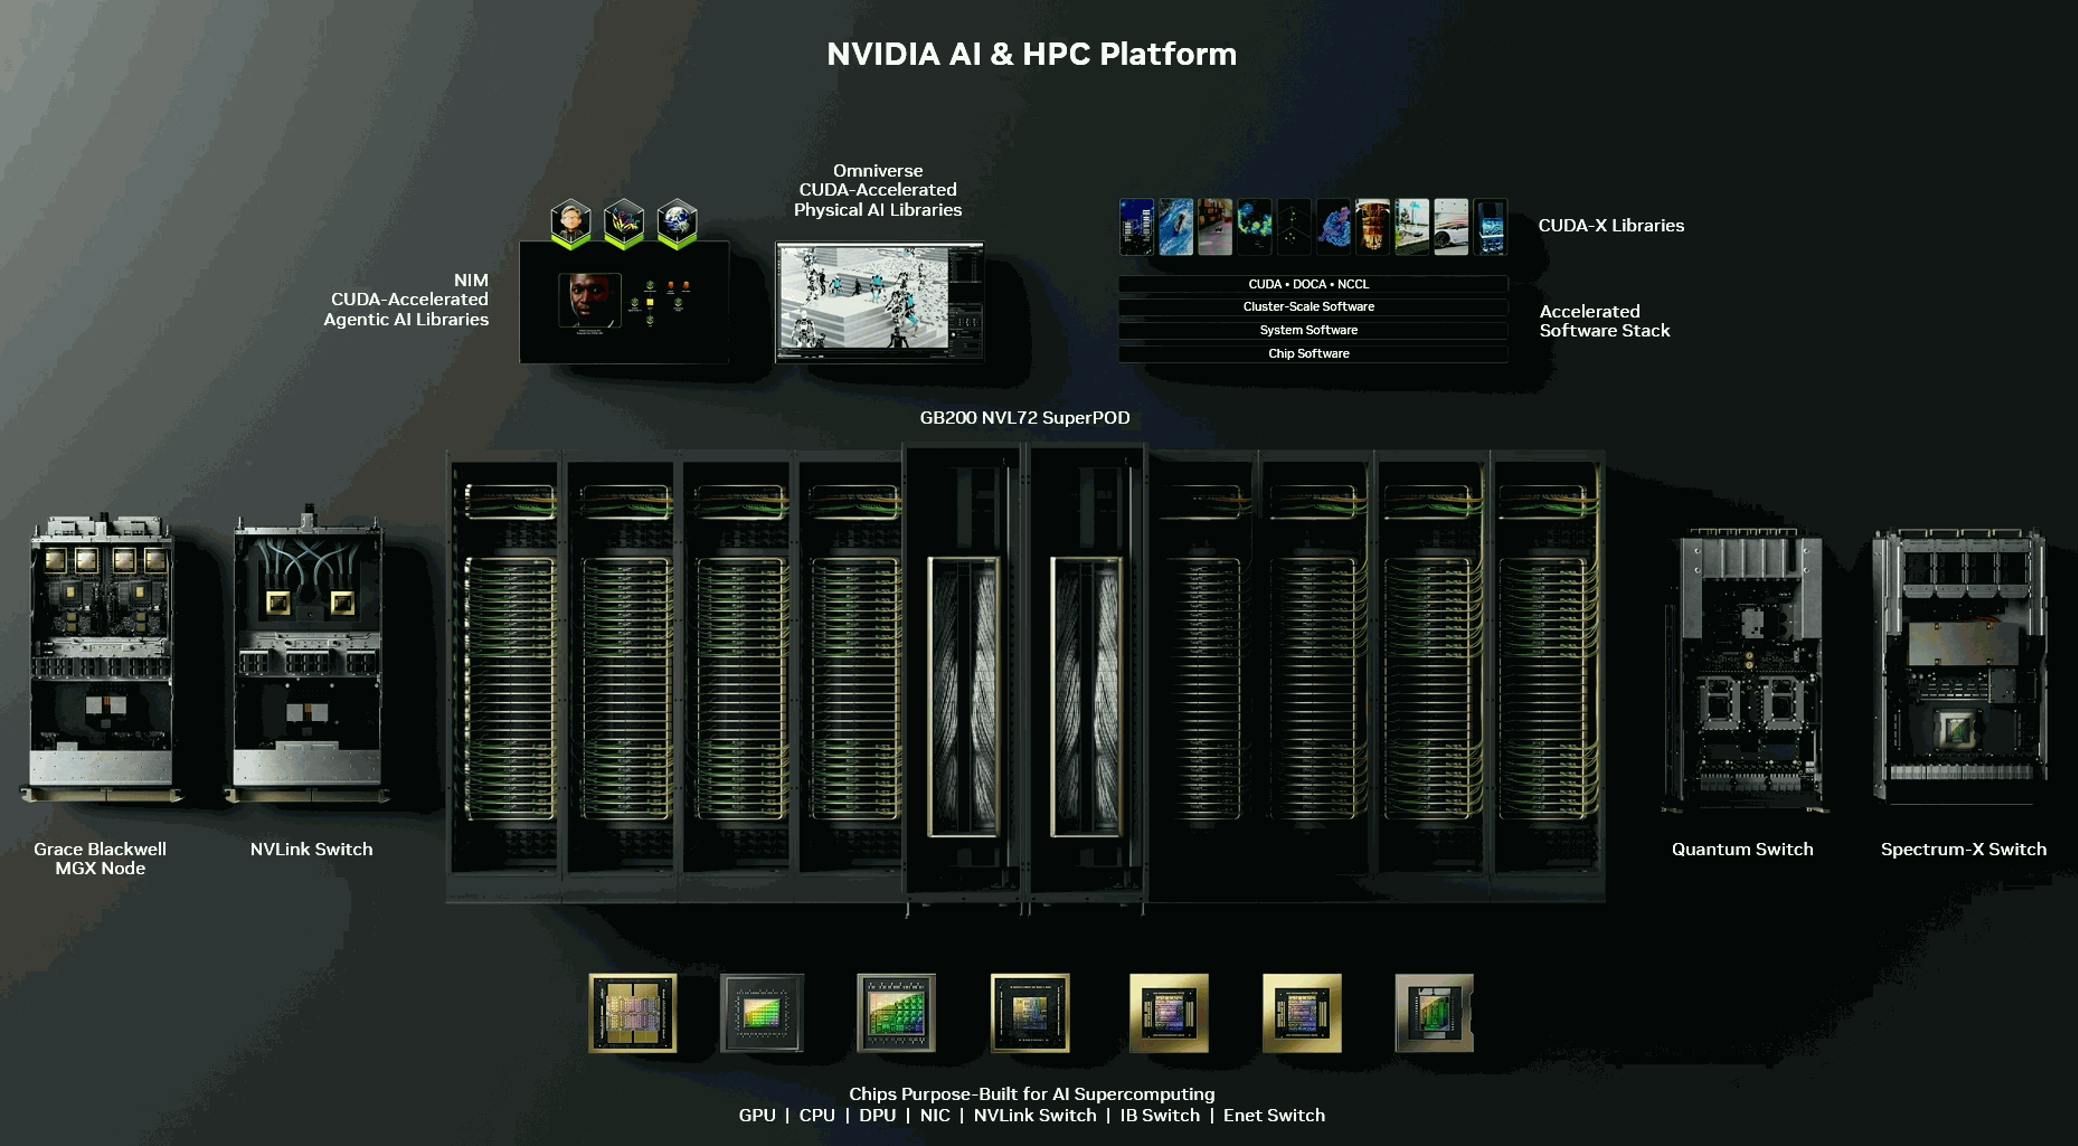
The NVIDIA Grace Blackwell 200 (GB200) Superchip combines two Blackwell GPUs and one Grace CPU. It’s NVIDIA’s first rack-scale product. The NVIDIA GB200 NVL72 is a configuration and rack-scale, liquid-cooled AI computing platform, which is purpose-built for AI training and inferencing, handling up to 27 trillion parameters for generative AI models. The GB200 includes base components like Grace Hopper compute trays, NVLink switches (a connector in the middle of the rack linking all GPUs) and cable cartridges (literally miles of cables in the back to tie everything together). The design includes quantum switches for InfiniBand (a high-speed network for linking clusters) and spectrum switches for Ethernet.
AI 101: What are Clusters and Superclusters?
Clusters 101: are a network of independent computers (called nodes) connected by a high-speed network. A cluster serves as a unified resource, as they are separate machines configured to work together to act as a single powerful computing system. They are often used for parallel processing, which breaks down a large task into smaller parts distributed across the nodes, enabling faster processing than just a single computer could do. A key benefit of a node is high availability, meaning if one node (computer) fails, the other nodes can take over its workload, ensuring that the system remains operational. High-performance compute (HPC) clusters are used for tasks like research, scientific simulations and AI training.
Join thousands of investors who trust I/O Fund’s expert stock analysis on AI, semiconductors, cryptocurrency, and adtech — sign up for free! Click here!
Superclusters 101: are very large clusters that may be comprised of hundreds to thousands of GPUs through many data centers. For example, Elon Musk’s xAI supercomputer Colossus, powered by 100,000 NVIDIA GPUs, is definitely a supercluster.
DGX started as single machines for AI but evolved into clusters for AI training. Pre-training can involve superclusters, but post-training can still involve 16,000 GPUs with smaller setups for fine-tuning and inference using trained AI to answer questions.
Optimizing the Benefits of Rack-Scale Architecture with GB200
NVIDIA’s GB200 NVL72 is a rack-scale system. Rack-scale designs a whole rack as one big, coordinated unit, not just random machines stuck together. Rack scale refers to integrating and compressing systems that may span across multiple servers, storage and networking devices onto a single server rack. GB200 can replace or consolidate a large number of GPU compute servers. This provides many benefits, including:
- Improved GPU Density: The GB200 NVL72 contains 72 Blackwell GPUs, and 36 Grace CPUs interconnected with NVLink, NVIDIA’s proprietary high-speed (130 TB/s) signaling interconnect that enables all 72 GPUs and 36 CPUs to act as a single massive GPU. It’s designed to offer exceptional performance in AI training and inference for large language models (LLMs).
- Performance: The GB200 delivers up to 720 petaFLOPs for AI training and 1.4 exaFLOPs for inference. Since all components are within proximity in a single rack, communication between components has much lower latency, which is especially beneficial in data-intensive tasks, reducing bottlenecks and improving data throughput.



